Copy Files Between Disk, Network Share and Cloud
A console tool driven by one config file, built on one storage abstraction
Every team accumulates little file-moving chores. Copy last night's exports to the NAS. Push product images to blob storage. Keep a local mirror of scanned invoices. Each one starts life as a one-line script, grows retry logic and logging, gets cloned for the next chore with slightly different paths, and two years later there are nine scripts, no two alike, and nobody remembers which ones still run.
This article builds the alternative once: a small .NET console tool where a sync job is pure configuration — a source, one or more targets, an optional file filter — and a new chore is a new JSON block rather than new code. The tool is about six short C# files, because the heavy lifting sits behind one abstraction. That abstraction is the subject of the first part of this series; read the tip first if IFileService and identifiers are new to you.
Universal or Regira? Jobs as configuration and a copy-if-missing loop are the tool, and they are yours to keep; the IFileService seam underneath is Regira.IO.Storage, and swapping in another storage abstraction is one factory class.
The abstraction underneath
Regira.IO.Storage puts one IFileService in front of the local disk, credentialed network shares, Azure Blob Storage, SFTP and more. Every method speaks in identifiers, paths relative to the service's root, so the same identifier means "this file" on every backend; the tip covers the interface and that rule.
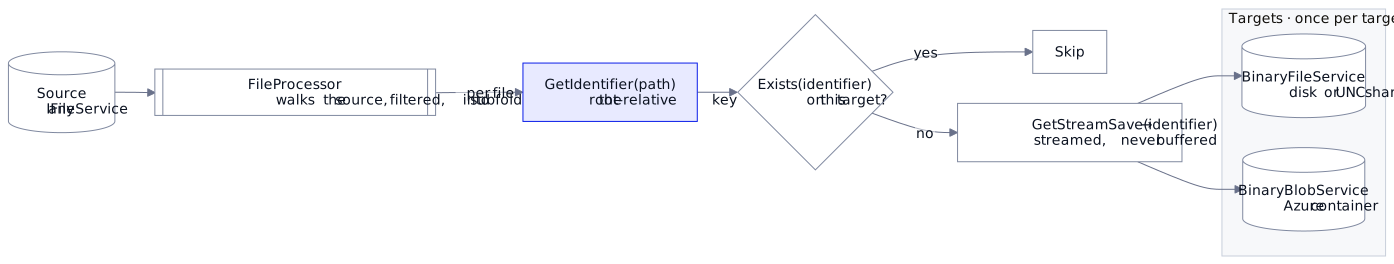
Beyond Exists, GetStream and Save, the tool leans on one helper: GetIdentifier(path) converts whatever absolute form a directory walk yields back into the portable relative key. Read an identifier from the source, write the same identifier to the target, and the folder structure comes along for free.
Jobs as configuration
Working backwards from the config we want to write:
// appsettings.json
"Sync": [
    {
        "Source": {
            "FileSystem": { "RootFolder": "C:\\Exports\\Photos" },
            "FileSearchObject": { "Extensions": [ ".jpg", ".jpeg", ".png" ] }
        },
        "Targets": [
            { "FileSystem": { "RootFolder": "F:\\Backup\\Photos" } },
            { "Azure": { "ConnectionString": "<secret>", "ContainerName": "photos" } }
        ]
    },
    {
        "Source":  { "FileSystem": { "RootFolder": "C:\\Scans" } },
        "Targets": [ { "FileSystem": { "RootFolder": "\\\\nas\\archive\\scans" } } ]
    }
]
A list of jobs; each job one source and n targets; the source optionally filtered. The options classes mirror it exactly, and one convention keeps the config honest: a StorageOptions block declares one property per supported backend, and whichever one is present decides the implementation:
public class SyncOptions : List<SyncJobOptions>;

public class SyncJobOptions
{
    public SourceStorageOptions Source { get; set; } = null!;
    public ICollection<StorageOptions> Targets { get; set; } = new HashSet<StorageOptions>();
}

public class StorageOptions
{
    public FileSystemOptions? FileSystem { get; set; }
    public AzureOptions? Azure { get; set; }
    // add more storage option implementations here
}

public class SourceStorageOptions : StorageOptions
{
    public FileSearchObject? FileSearchObject { get; set; }
}
- No
"Type": "azure"discriminator to keep in sync with an enum. The presence of theAzurekey is the discriminator. FileSystemOptions,AzureOptionsandFileSearchObjectare the library's own option types, so configuration binds straight into them.
A tiny factory turns an options block into a live service:
public class StorageFileServiceFactory : IStorageFileServiceFactory
{
    public IFileService Create(StorageOptions options)
    {
        if (options.FileSystem != null)
            return new BinaryFileService(options.FileSystem);
        if (options.Azure != null)
            return new BinaryBlobService(new AzureCommunicator(options.Azure));
        // Add more storage options here
        throw new NotSupportedException();
    }
}
(The IStorageFileServiceFactory, ISyncJobManager and ISyncManager interfaces are the one-method mirrors of the classes that implement them — declared for DI, elided here.)
The sync loop
With everything storage-specific behind IFileService, the synchronization itself is almost disappointingly small. FileProcessor, a helper from the same package, walks the source — recursively, applying the job's FileSearchObject filter — and invokes a callback per file:
public class SyncJobManager(IStorageFileServiceFactory factory, ILogger<SyncJobManager> logger)
    : ISyncJobManager
{
    public Task Sync(SyncJobOptions options)
    {
        var sourceService = factory.Create(options.Source);
        var fileProcessor = new FileProcessor(sourceService);
        var targetServices = options.Targets.Select(factory.Create).ToList();

        return fileProcessor.ProcessFiles(
            options.Source.FileSearchObject ?? new FileSearchObject(),
            async (path, fileService) =>
            {
                var identifier = fileService.GetIdentifier(path);
                foreach (var target in targetServices)
                {
                    if (await target.Exists(identifier)) continue;
                    try
                    {
                        await using var stream = await fileService.GetStream(identifier);
                        await target.Save(identifier, stream!);
                        logger.LogInformation("Copied {Identifier} to {Root}", identifier, target.Root);
                    }
                    catch (Exception ex)
                    {
                        logger.LogError(ex, "Copying {Identifier} to {Root} failed", identifier, target.Root);
                    }
                }
            }, true);
    }
}
The details that carry the weight:
ExistsbeforeSavemakes the tool copy-if-missing, and therefore idempotent: run it hourly, run it after a crash, run two jobs overlapping the same target — files already present are skipped, so a rerun costs one existence check per file per target. It also defines what the tool is not: it will not overwrite changed files or delete removed ones. A true mirror compares timestamps or hashes and is a deliberate step up in destructive potential — a good v2, not a default..ToList()on the targets. A lazySelectwould build fresh target services for every file, and on Azure each fresh one checks its container again: two round trips per file instead of one.- Streams, not byte arrays.
GetStream→Save(stream)pipes each file through without ever holding it in memory, which is the difference between "works on my test folder" and "works on 40 GB of video".
The per-file try/catch means one unreadable file logs an error and the run continues; for a nightly batch job, resilience beats fail-fast.
One more small class fans out over the configured jobs:
public class SyncManager(IOptions<SyncOptions> options, ISyncJobManager manager) : ISyncManager
{
    public async Task Sync()
    {
        foreach (var job in options.Value)
            await manager.Sync(job);
    }
}
Hosting
The entry point is a standard Generic Host console, worth having even for a small tool because it buys configuration layering, DI and real logging for a dozen lines. The three Add* calls are small extension methods wrapping the standard APIs; they are in the sample's HostExtensions.cs:
using var host = Host.CreateApplicationBuilder(args)
    .AddConfiguration()   // env vars + appsettings.json + user secrets (Debug)
    .AddServices()        // Configure<SyncOptions>(config.GetSection("Sync")) + the services above
    .AddSerilog()         // wraps Services.AddSerilog, reading the "Serilog" config section
    .Build();

using var scope = host.Services.CreateScope();
var sm = scope.ServiceProvider.GetRequiredService<ISyncManager>();
await sm.Sync();
One habit to keep from the setup: secrets stay out of the committed appsettings.json. User secrets carry the Azure connection string in development, environment variables in production, and the JSON never holds more than a placeholder.
Run it, extend it
The tool is packaged to run — grab the sample project: the six files, a demo job syncing a bundled data/source folder into data/mirror, and a README. dotnet run gives, on the first run (file order may differ):
[HH:mm:ss INF] Start
[HH:mm:ss INF] Copied hello.txt to <...>/data/mirror
[HH:mm:ss INF] Copied invoices/inv-001.txt to <...>/data/mirror
[HH:mm:ss INF] Copied docs/guide.md to <...>/data/mirror
[HH:mm:ss INF] Finished
Run it again and no Copied lines appear — Exists before Save at work.
The shape of the tool dictates the shape of every future change:
- New chore? A new JSON block. No build, no deploy.
- New backend? One nullable property on
StorageOptions, one branch in the factory — SFTP isSftpServiceover anSftpCommunicatorbuilt fromSftpConfig, inRegira.IO.Storage.SSH; set the config'sHostKeyFingerprint(asssh-keygen -lfprints it), or the tool trusts whichever server answers at that address. The sync loop never knew about backends to begin with. - Narrower sources?
FileSearchObjectalready filters by folder and extension list, so "only PDFs underinvoices/" is configuration too.
Why not a script per chore? A script is the right size for the first chore and the wrong size for the ninth: each copy carries its own paths, its own retry logic and its own logging, and they drift apart. Here the variation — the backends — sits behind one interface keyed by portable identifiers, the intent — the jobs — sits in configuration, and the code that remains is a short, uneventful loop you never need to clone again.
Docs: regira.github.io/Regira-Packages — IO.Storage (Apache-2.0).
Versions: the sample runs on the .NET 10 SDK and pins Regira.IO.Storage and Regira.IO.Storage.Azure 6.3.2. Since 6.3 the storage packages no longer pull the generic host in behind them, so Microsoft.Extensions.Hosting is an explicit reference in the .csproj, beside the Serilog and user-secrets packages. SftpConfig.HostKeyFingerprint arrived in 6.5.0; through 6.4.0 the SFTP backend accepted any host key.